China Data Compliance Cost Survey 2026
How much does data compliance actually cost in China? Five years after the Personal Information Protection Law (PIPL) took effect and four years after the Data Security Law, companies have moved from “what do we need to do?” to “what does this all cost?” — but reliable cost benchmarks have been hard to find.
This survey of 62 companies — including 23 foreign-invested enterprises, 28 domestic tech companies, and 11 large non-tech enterprises — provides a detailed look at what companies are spending on data compliance in China, how they are organising their compliance functions, and where they see costs heading.
Survey Methodology
The survey was conducted between March and June 2026, with respondents from companies operating in China across multiple sectors: technology and AI, e-commerce, financial services, healthcare, manufacturing, and consumer goods. Company sizes ranged from early-stage startups (fewer than 50 employees) to large enterprises with more than 5,000 employees in China.
All cost figures are annual data compliance spending for China operations, including personnel, technology, external services, and compliance-related infrastructure costs. Figures are in RMB unless otherwise noted.
Total Compliance Spending
Total annual data compliance spending varies widely depending on company size, data volume, and industry. Here is the overall distribution.
| Company Size | Median Annual Spend | Range | Spending as % of Revenue |
|---|---|---|---|
| Startup (<100 employees) | ¥150,000 | ¥50,000 – 400,000 | 1.5 – 3.5% |
| Mid-size (100-500) | ¥550,000 | ¥250,000 – 1,500,000 | 0.8 – 2.0% |
| Large (500-2,000) | ¥1,800,000 | ¥800,000 – 4,000,000 | 0.4 – 1.0% |
| Enterprise (2,000+) | ¥5,500,000 | ¥2,000,000 – 15,000,000 | 0.2 – 0.6% |
As a percentage of revenue, data compliance spending follows the classic pattern: smaller companies spend a higher share, while larger companies achieve economies of scale. Startups and early-stage companies spend 1.5-3.5% of revenue on data compliance — a significant burden that reflects both the high fixed cost of compliance and the limited resources of small teams.
For AI companies specifically, the numbers are higher than average. AI companies in our survey spend approximately 30-50% more on data compliance than non-AI tech companies of similar size, due to the additional complexity of AI-specific data issues (training data, model inference data, automated decision-making, and biometric data processing).
Cost Breakdown
Where does the money go? The cost of data compliance breaks down into several categories.
| Cost Category | Share of Total | Typical Range (mid-size co.) |
|---|---|---|
| Personnel (in-house team) | 35-50% | ¥200,000 – 800,000 |
| External legal & consulting | 20-30% | ¥100,000 – 450,000 |
| Technology & tools | 15-25% | ¥80,000 – 350,000 |
| Training & awareness | 3-8% | ¥15,000 – 60,000 |
| Audit & assessment | 5-12% | ¥30,000 – 150,000 |
| Other (incident response, etc.) | 2-7% | ¥10,000 – 80,000 |
Personnel is the largest cost category for most companies. Even companies that outsource most of their compliance work still need at least one internal person to manage the function, coordinate with external advisors, and ensure day-to-day compliance.
Technology spending has been growing faster than any other category — up approximately 35% since 2024. Companies are investing in data classification tools, consent management platforms, data loss prevention systems, and privacy-enhancing technologies. This trend is expected to continue as compliance becomes more automated.
Industry Comparison
Data compliance costs vary significantly by industry, driven by differences in data volume, data sensitivity, and regulatory intensity.
| Industry | Median Annual Spend (mid-size) | Key Cost Driver |
|---|---|---|
| Financial services | ¥1,200,000 | High regulation, sensitive data |
| Healthcare / medical | ¥1,000,000 | Health data, strict requirements |
| AI / technology | ¥750,000 | Training data, complex processing |
| E-commerce | ¥700,000 | Large customer data volumes |
| Consumer / retail | ¥450,000 | Customer data, marketing |
| Manufacturing | ¥350,000 | Employee data, supply chain data |
| B2B SaaS | ¥300,000 | Moderate data volume |
Financial services and healthcare top the list, as expected — they handle the most sensitive personal information and face the most stringent regulatory requirements. AI and tech companies are in the middle of the pack in absolute terms but high relative to their size, reflecting the complexity of AI data compliance.
Cross-Border Data Transfer Costs
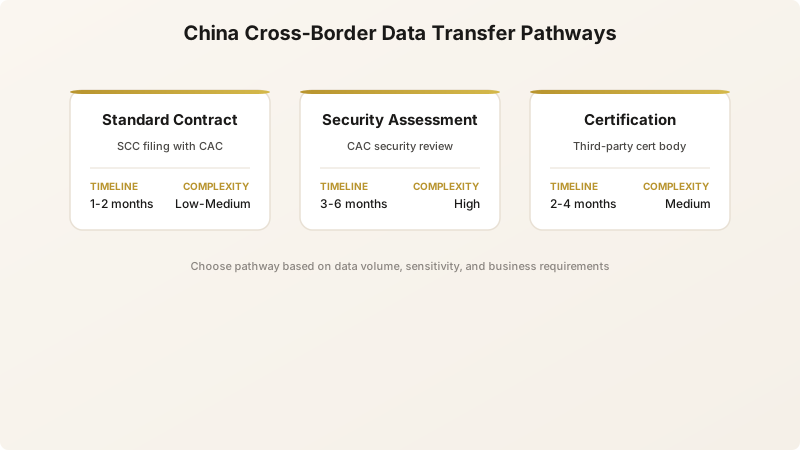
Cross-border data transfer is one of the most expensive — and most common — compliance challenges for foreign-invested companies. Of the foreign companies in our survey, 78% had at least one cross-border data transfer pathway set up, and 35% had multiple pathways for different data types.
| Transfer Pathway | Setup Cost | Annual Maintenance | Typical Timeline |
|---|---|---|---|
| Standard Contract (SCC) | ¥30,000 – 80,000 | ¥10,000 – 30,000 | 1-2 months |
| Security Assessment | ¥80,000 – 200,000 | ¥30,000 – 80,000 | 3-6 months |
| Certification | ¥100,000 – 300,000 | ¥50,000 – 150,000 | 4-8 months |
The standard contract pathway is by far the most common, used by 61% of companies with cross-border transfers. Security assessment is used by 27%, mostly by larger companies transferring large volumes of data. Certification — the newest pathway — is used by only 12% of companies, but adoption is growing as the process becomes better established.
Many companies underestimate the ongoing maintenance cost of cross-border transfers. Standard contracts need to be reviewed and updated when there are material changes to the data processing activities. Security assessments require periodic renewal. And all pathways require ongoing monitoring and documentation to demonstrate continued compliance.
Team Structure
How do companies organise their data compliance function? The model varies by company size.
| Company Size | In-House Team Size | Outsourcing Model |
|---|---|---|
| Startup (<100) | 0-1 person (often part-time) | Heavy outsourcing |
| Mid-size (100-500) | 1-3 people | Mixed — core in-house, project work outsourced |
| Large (500-2,000) | 3-8 people | Moderate outsourcing for specialised work |
| Enterprise (2,000+) | 10-30+ people | Primarily in-house with specialist advisors |
The trend is toward more in-house capability over time. Companies that initially outsource everything typically bring more functions in-house as they grow and their compliance needs become more complex. The functions that stay outsourced are usually specialised legal advice, regulatory filing support, and formal audits — areas where external expertise remains essential.
For foreign-invested companies specifically, there is often a dual structure: a local China compliance team that handles day-to-day compliance, plus a global privacy or legal team that sets global standards and ensures alignment across jurisdictions. The coordination between local and global teams is itself a cost — both in time and in potential friction when global standards and local requirements conflict.
Technology Investment
Compliance technology is the fastest-growing cost category. What are companies spending on?
| Technology / Tool | Adoption Rate | Typical Annual Cost |
|---|---|---|
| Data classification tools | 42% | ¥50,000 – 200,000 |
| Consent management platform | 35% | ¥30,000 – 150,000 |
| Data subject rights portal | 28% | ¥20,000 – 100,000 |
| Data loss prevention (DLP) | 24% | ¥80,000 – 300,000 |
| Privacy impact assessment tools | 19% | ¥30,000 – 120,000 |
| Data mapping / inventory tools | 17% | ¥40,000 – 180,000 |
| Encryption / security tools | 56% | ¥60,000 – 250,000 |
Encryption and general security tools have the highest adoption rate, which makes sense — they address both data security requirements and general cybersecurity needs. Data classification tools, consent management platforms, and data subject rights portals are seeing rapid growth as companies move from basic compliance to more mature programmes.
Notably, many companies still rely heavily on manual processes — especially for data mapping, impact assessments, and records of processing activities. As compliance requirements become more demanding and companies grow, manual processes become increasingly unsustainable, driving investment in automation tools.
Training and Awareness
Employee training is often seen as a checkbox exercise, but it is a critical part of a defensible compliance programme.
| Training Type | Adoption Rate | Frequency | Typical Cost / Year |
|---|---|---|---|
| General data protection awareness | 71% | Annual | ¥5,000 – 30,000 |
| Role-specific training (engineers, HR) | 44% | Annual + onboarding | ¥10,000 – 50,000 |
| Executive / management training | 38% | Annual | ¥5,000 – 25,000 |
| New hire onboarding training | 62% | Ongoing | Included in HR onboarding |
| Phishing / security awareness | 58% | Quarterly | ¥3,000 – 20,000 |
Companies with mature compliance programmes invest in more than just annual online training. They do role-specific training — engineers get training on data security in product development, HR gets training on employee data handling, marketing gets training on customer data and consent. They also do regular phishing simulations and security exercises.
The cost of training is relatively modest compared to other compliance categories, but the return on investment can be high. Human error is a factor in most data security incidents — well-trained employees are one of the best defences.
Cost Trends and Outlook
Looking ahead, where are data compliance costs heading? Our survey respondents expect costs to continue rising, but at a slower pace than the initial implementation phase.
| Year | Estimated Change in Compliance Spend | Primary Driver |
|---|---|---|
| 2021 | +35-50% | PIPL implementation |
| 2022 | +25-40% | DSL implementation + enforcement |
| 2023 | +15-25% | Cross-border transfer rules |
| 2024 | +10-20% | Enforcement deepening + AI data rules |
| 2025 | +8-15% | AI regulation expansion |
| 2026 (est.) | +5-12% | Ongoing enforcement + technology investment |
| 2027 (proj.) | +3-8% | Maturing programmes, more automation |
The rapid cost increase of 2021-2023 — driven by initial PIPL and DSL implementation — has moderated as companies have built their basic compliance programmes. Current cost growth is driven by two factors: deepening enforcement (which pushes companies to invest in more robust compliance) and technology investment (as companies automate manual processes).
Looking forward to 2027 and beyond, we expect cost growth to continue moderating as compliance programmes mature and automation delivers efficiency gains. But we do not expect costs to go down — new regulations, expanding scope, and increasing enforcement will keep pushing spending up, just at a slower rate.
Key Findings
Data compliance is a significant cost — but it is table stakes. Even small companies spend hundreds of thousands of yuan per year. For companies handling sensitive personal data or large volumes of data, the cost runs into millions. But the cost of non-compliance — fines, reputational damage, business disruption — is much higher.
The cost structure is shifting from services to technology. Initially, companies spent most of their compliance budget on external lawyers and consultants to figure out what to do and set up basic programmes. As programmes mature, more spending goes to internal teams and technology tools.
Automation is the next frontier. Many compliance processes are still manual — data mapping, impact assessments, records of processing activities, data subject request handling. Companies that automate these processes can reduce long-term costs and improve consistency.
AI companies face higher compliance costs. The combination of training data complexity, automated decision-making, biometric data processing, and algorithm filing requirements means AI companies spend 30-50% more on data compliance than non-AI tech companies of similar size.
Mature programmes cost less in the long run. Companies that invest in building solid compliance programmes — with clear policies, trained employees, good documentation, and appropriate technology — tend to have lower total compliance costs over time than companies that take a reactive, minimum-compliance approach. They are also better positioned to handle new regulatory requirements as they emerge.
This survey is based on anonymised data from 62 companies operating in China, collected between March and June 2026. All figures are approximate and for general informational purposes only. Actual compliance costs depend on specific circumstances including company size, industry, data volume, and risk profile.
Privacy by Design: Building Compliance into the Product
Privacy by design is the principle of building data protection into products and systems from the earliest stages, rather than adding it as an afterthought. For AI companies entering China, this is not just a best practice — it is increasingly an expectation under PIPL and related regulations.
Practical privacy by design measures include: data minimisation (collecting only what you need), purpose limitation (not repurposing data without new consent), default privacy settings (starting with the most protective configuration), and privacy impact assessments for high-risk processing activities. For AI products specifically, it also means thinking about things like federated learning (training models without centralising data), differential privacy (adding noise to protect individual records), and on-device processing where feasible.
The business case for privacy by design is strong. Companies that build compliance in early spend less on remediation later, face lower regulatory risk, and often find that the discipline of thinking through data flows improves their product architecture. It is also a strong signal to customers, partners, and regulators that you take data protection seriously.
Data Retention: How Long to Keep What, and Why
Data retention is one of those compliance areas that seems simple but gets complicated quickly. The basic principle is straightforward: you should not keep personal data longer than you need it for the purposes for which you collected it. But figuring out exactly how long you need to keep different types of data — and then actually implementing those retention periods in your systems — is the hard part.
Different types of data have different retention drivers. Some are driven by legal requirements (tax records must be kept for 10 years in China, employment records for a certain period after employment ends). Some are driven by business needs (customer data for as long as the customer relationship is active, plus a reasonable period afterwards). Some are driven by security and compliance (access logs, audit trails).
The best approach is to build a data retention schedule that lists each data category, the retention period, the reason for the retention period, and what happens at the end of the period (deletion, anonymisation, archiving). Then you need to implement this schedule in your systems — which can be technically challenging, especially for complex data ecosystems. But having clear policies and making reasonable efforts to implement them goes a long way toward compliance.
Data Subject Rights: From Policy to Operations
PIPL grants data subjects several rights: the right to know and decide, the right to access and copy, the right to correct, the right to delete (the ‘right to be forgotten’), the right to data portability, and the right to explanation for automated decision-making. Having these rights listed in your privacy policy is necessary but not sufficient — you need operational processes to actually fulfil them.
Setting up a data subject rights process involves several components: a clear intake channel (usually an email address or web form), identity verification procedures, standard timelines for responding (PIPL requires responses within a reasonable period, typically interpreted as 15-30 working days), procedures for verifying and fulfilling different types of requests, and an escalation process for complex or unusual requests.
For AI companies, some rights raise specific challenges. The right to explanation for automated decision-making, for example, requires thinking about what you can actually explain about your AI system’s decisions without disclosing proprietary information. The right to delete can be complicated when personal information has been used to train models — can you truly delete someone’s data from a trained model? These are areas where the law is still evolving, and you need processes that are flexible enough to adapt as expectations become clearer.
Data Classification and Grading: The Decision Framework
Data classification and grading is the process of categorising your data by type and sensitivity level — a foundational requirement under China’s Data Security Law. The system has three main levels: ordinary data, important data, and core data — each with progressively stricter security and transfer requirements.
For most foreign AI companies, the question is not whether you have core data (most do not), but whether any of your data counts as ‘important data’ — a category that triggers additional security obligations and stricter cross-border transfer rules. The definition of important data is sector-specific and still evolving, but it generally includes data that, if compromised, could harm national security, public interests, or economic development.
The classification process itself is valuable beyond just compliance. It forces you to think about what data you have, why you have it, and what would happen if it were lost or exposed. This understanding helps you prioritise security investments, allocate resources appropriately, and make better decisions about data retention and access controls.
Vendor and Sub-Processor Data Compliance
When you use third-party vendors and sub-processors that handle personal data on your behalf, you are still responsible for that data’s protection. Under PIPL, data controllers have specific obligations when entrusting data processing to third parties — including written agreements, supervision of the processor, and ensuring the processor meets security requirements.
A robust vendor data compliance programme includes several elements: due diligence before engaging a vendor (assessing their security practices and compliance track record), clear data processing agreements (specifying the scope, purpose, duration, security measures, and both parties’ obligations), ongoing monitoring (periodic audits, security reviews), and exit procedures (ensuring data is returned or deleted when the relationship ends).
For AI companies, this is especially important because you likely have many vendors — cloud providers, analytics tools, customer support platforms, development tools — and each one touches your data in different ways. Mapping all your vendors and their data access, then ensuring each relationship has the right contractual protections, is a significant but necessary compliance effort.
PIPL Enforcement: What Foreign Companies Get Wrong
Since the Personal Information Protection Law (PIPL) took effect in 2021, enforcement has steadily increased in both frequency and sophistication. Looking at the cases from 2025 and early 2026, several patterns emerge about where foreign companies tend to slip up.
The most common issue is not consent collection itself — most companies have a consent mechanism — but rather the quality and specificity of that consent. Regulators increasingly scrutinise whether consent is truly informed, freely given, and specific to each processing purpose. Bundled consent, where users agree to everything in one click, is increasingly challenged.
Second, foreign companies often underestimate their obligations around sensitive personal information. Biometric data, health data, financial information, and children’s data each have heightened requirements, including separate consent and additional security measures. AI products that process face data or voice data, in particular, need to plan for these enhanced obligations from the design phase.
Third, data subject rights — access, correction, deletion, and portability — need operational implementation, not just a policy statement. Regulators expect companies to have actual processes for responding to data subject requests within the statutory time limits.
Data Localisation vs. Cross-Border: Strategic Tradeoffs
One of the most consequential decisions for a foreign company entering China is where to store and process data. Full data localisation — keeping all data within mainland China — simplifies compliance with PIPL and data security rules but increases infrastructure cost and complicates global product development.
A more nuanced approach is to segment your data by type and risk. Core personal information and sensitive data may need to stay in China by default, with cross-border transfers only when necessary and through an approved pathway. Non-personal, aggregated, or anonymised data may have more flexibility.
The decision also depends on your architecture. Companies with a single global database tend to default to cross-border transfer pathways, which means more compliance work upfront. Companies that design a China-specific data layer from the start often have an easier time, even though the engineering investment is higher. There is no universally right answer — the optimal approach balances compliance risk, engineering cost, and business flexibility.
Data Breach Response: Planning for When It Happens
No company wants to experience a data breach, but the reality is that even well-protected companies can have security incidents. The difference between a manageable incident and a catastrophic one is usually how prepared you are.
Under PIPL and the Data Security Law, companies have specific obligations when a data security incident occurs: they must take immediate remedial measures, notify affected users, and report to the relevant authorities. The specific notification requirements and timelines depend on the type and severity of the incident.
A good data breach response plan should include: a clear incident response team with defined roles, procedures for containing and assessing the incident, notification workflows (who to notify, when, and what to say), regulatory reporting procedures, and a post-incident review process. The plan should be tested regularly through tabletop exercises — because discovering gaps in your plan during an actual incident is much more expensive than finding them in a simulation.
Related Articles
- China’s Network Data Security Regulation Takes Effect
- Network Data Security Risk Assessment Measures: Annual Assessment for Processors
- Technology Export and Data Export: Running Two Regimes in Parallel
- Four Departments Move to Cultivate Data-Circulation Service Institutions
FAQ
Q: How much does data compliance cost for a startup in China?
A: For a typical tech startup with fewer than 100 employees, annual data compliance spending is typically ¥150,000 on average, with a range of ¥50,000 to ¥400,000. As a percentage of revenue, this is 1.5-3.5% — a significant burden for early-stage companies. The cost includes basic legal advice, privacy policy drafting, data mapping, and either a part-time in-house compliance person or ongoing advisory support.
Q: What is the biggest cost driver in data compliance?
A: Personnel is usually the largest single cost category — 35-50% of total compliance spending. Even companies that outsource most of the work still need at least one internal person to manage the function. Technology is the fastest-growing category, up about 35% since 2024, as companies invest in data classification tools, consent management platforms, and automation. External legal and consulting services are also a significant cost, especially for companies building their compliance programmes.
Q: How much does cross-border data transfer compliance cost?
A: It depends on the pathway. Standard contract filing, the most common pathway, typically costs ¥30,000-80,000 to set up plus ¥10,000-30,000 per year in maintenance. Security assessment, for larger or more sensitive data transfers, costs ¥80,000-200,000 to set up plus ¥30,000-80,000 per year. Certification, the least common pathway, has the highest upfront cost but longer validity.
Q: Are compliance costs still rising or have they stabilised?
A: Costs are still rising but at a slower rate. The rapid cost increases of 2021-2023 — when PIPL and DSL first took effect — have moderated. Current cost growth of 5-12% per year is driven by deepening enforcement, new AI-related data requirements, and technology investment. We expect growth to continue moderating as compliance programmes mature and automation delivers efficiency gains.
Q: How do AI companies’ compliance costs compare to other tech companies?
A: AI companies spend approximately 30-50% more on data compliance than non-AI tech companies of similar size. The additional cost comes from several factors: training data compliance (complex data sourcing and licensing), model inference data (real-time processing of large volumes of user data), automated decision-making (transparency and accountability requirements), biometric data processing (for many AI applications involving face, voice, or health data), and algorithm filing requirements.
Frequently Asked Questions↑ Back to article
How much does data compliance cost for a startup in China?
For a typical tech startup with fewer than 100 employees, annual data compliance spending is typically ¥150,000 on average, with a range of ¥50,000 to ¥400,000. As a percentage of revenue, this is 1.5-3.5% — a significant burden for early-stage companies. The cost includes basic legal advice, privacy policy drafting, data mapping, and either a part-time in-house compliance person or ongoing advisory support.
What is the biggest cost driver in data compliance?
Personnel is usually the largest single cost category — 35-50% of total compliance spending. Even companies that outsource most of the work still need at least one internal person to manage the function. Technology is the fastest-growing category, up about 35% since 2024, as companies invest in data classification tools, consent management platforms, and automation. External legal and consulting services are also a significant cost, especially for companies building their compliance programmes.
How much does cross-border data transfer compliance cost?
It depends on the pathway. Standard contract filing, the most common pathway, typically costs ¥30,000-80,000 to set up plus ¥10,000-30,000 per year in maintenance. Security assessment, for larger or more sensitive data transfers, costs ¥80,000-200,000 to set up plus ¥30,000-80,000 per year. Certification, the least common pathway, has the highest upfront cost but longer validity.
Are compliance costs still rising or have they stabilised?
Costs are still rising but at a slower rate. The rapid cost increases of 2021-2023 — when PIPL and DSL first took effect — have moderated. Current cost growth of 5-12% per year is driven by deepening enforcement, new AI-related data requirements, and technology investment. We expect growth to continue moderating as compliance programmes mature and automation delivers efficiency gains.
How do AI companies' compliance costs compare to other tech companies?
AI companies spend approximately 30-50% more on data compliance than non-AI tech companies of similar size. The additional cost comes from several factors: training data compliance (complex data sourcing and licensing), model inference data (real-time processing of large volumes of user data), automated decision-making (transparency and accountability requirements), biometric data processing (for many AI applications involving face, voice, or health data), and algorithm filing requirements.
How does data compliance cost vary by company size in China?
Data compliance costs scale significantly with company size but decrease as a percentage of revenue. Startups with fewer than 100 employees spend a median of ¥150,000 per year, representing 1.5–3.5% of revenue. Mid-size companies with 100–500 employees spend a median of ¥550,000 or 0.8–2.0% of revenue. Large companies with 500–2,000 employees spend a median of ¥1,800,000 or 0.4–1.0% of revenue. Enterprise companies with 2,000+ employees spend a median of ¥5,500,000 or just 0.2–0.6% of revenue, reflecting economies of scale.
What are the main categories of data compliance spending in China?
The largest category is personnel, which accounts for 35–50% of total compliance spending, as even companies that outsource most work still need internal staff to manage the function. External legal and consulting services make up 20–30%, followed by technology and tools at 15–25%, which has been the fastest-growing category since 2024 as companies invest in data classification tools and consent management platforms. Smaller categories include training and awareness at 3–8%, audit and assessment at 5–12%, and other costs such as incident response at 2–7%.